LM-Kit.NET is an enterprise-grade toolkit designed for seamlessly integrating generative AI into your .NET applications, fully supporting Windows, Linux, and macOS. Empower your C# and VB.NET projects with a flexible platform that simplifies the creation and orchestration of dynamic AI agents.
Leverage efficient Small Language Models for on‑device inference, reducing computational load, minimizing latency, and enhancing security by processing data locally. Experience the power of Retrieval‑Augmented Generation (RAG) to boost accuracy and relevance, while advanced AI agents simplify complex workflows and accelerate development.
Native SDKs ensure smooth integration and high performance across diverse platforms. With robust support for custom AI agent development and multi‑agent orchestration, LM‑Kit.NET streamlines prototyping, deployment, and scalability—enabling you to build smarter, faster, and more secure solutions trusted by professionals worldwide.
Learn more

Gemini Enterprise Agent Platform is Google Cloud’s next-generation system for designing and managing advanced AI agents across the enterprise. Built as the successor to Vertex AI, it unifies model selection, development, and deployment into a single scalable environment. The platform supports a vast ecosystem of over 200 AI models, including Google’s latest Gemini innovations and popular third-party models. It offers flexible development tools like Agent Studio for visual workflows and the Agent Development Kit for deeper customization. Businesses can deploy agents that operate continuously, maintain long-term memory, and handle multi-step processes with high efficiency. Security and governance are central, with features such as agent identity verification, centralized registries, and controlled access through gateways. The platform also enables seamless integration with enterprise systems, allowing agents to interact with data, applications, and workflows securely. Advanced monitoring tools provide real-time insights into agent behavior and performance. Optimization features help refine agent logic and improve accuracy over time. By combining automation, intelligence, and governance, the platform helps organizations transition to autonomous, AI-driven operations. It ultimately supports faster innovation while maintaining enterprise-grade reliability and control.
Learn more
MiMo-V2.6-Pro
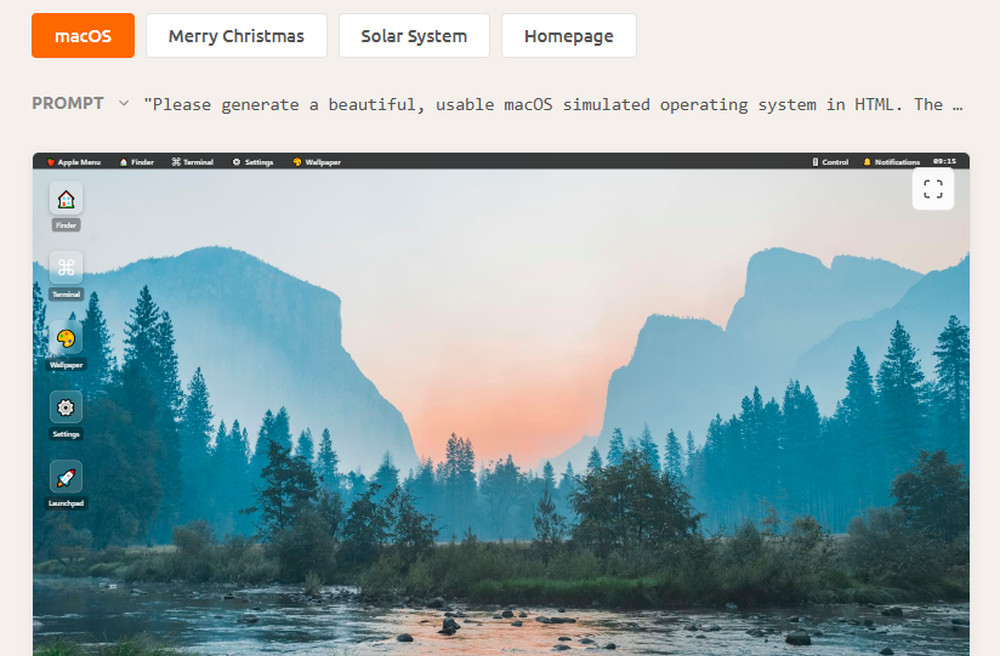
MiMo-V2.6-Pro is an open-source, natively omnimodal AI model from Xiaomi MiMo designed for coding, agentic workflows, visual creation, research, and computer-based tasks. It is the highest-capability model in the MiMo-V2.6 series and was trained using a large-scale reinforcement learning process focused on verifiable, complex tasks. The model can handle software engineering, automation, tool use, visual reasoning, and long-running agent workflows across multiple environments. Its multimodal capabilities extend beyond traditional coding into 3D scene generation, Blender modeling, embodied simulation, frontend development, presentation design, video creation, and music composition. MiMo-V2.6-Pro can take text, images, video, and other visual inputs and coordinate multi-agent workflows to produce and iteratively refine complex outputs. Research applications demonstrated by Xiaomi include materials discovery, literature analysis, computational simulation, hypothesis generation, and formalizing mathematical proofs in Lean. Xiaomi has released the model alongside its technical report, reinforcement learning environments, and RL code so researchers can study and reproduce the training approach. MiMo-V2.6-Pro is also available in an UltraSpeed configuration that provides substantially faster output for latency-sensitive workflows. Users can access the model through MiMo Desktop, AI Studio, MiMo Code, the MiMo API Platform, OpenRouter, and Hugging Face.
Learn more
Nemotron 3 Ultra
Nemotron 3 Nano is a small yet powerful large language model from NVIDIA's Nemotron 3 series, specifically crafted for effective agentic reasoning, interactive dialogue, and programming assignments. Its innovative Mixture-of-Experts Mamba-Transformer framework selectively activates a limited set of parameters for each token, ensuring rapid inference times without sacrificing accuracy or reasoning capabilities. With roughly 31.6 billion parameters in total, including about 3.2 billion active ones (or 3.6 billion when factoring in embeddings), it surpasses the performance of the previous Nemotron 2 Nano model while requiring less computational effort for each forward pass. The model is equipped to manage long-context processing of up to one million tokens, which allows it to efficiently process extensive documents, complex workflows, and detailed reasoning sequences in a single cycle. Moreover, it is engineered for high-throughput, real-time performance, making it particularly adept at handling multi-turn dialogues, invoking tools, and executing agent-based workflows that involve intricate planning and reasoning tasks. This versatility positions Nemotron 3 Nano as a leading choice for applications requiring advanced cognitive capabilities.
Learn more