Average Ratings 0 Ratings
Average Ratings 0 Ratings
Similar Products
-
Google AI StudioGoogle AI Studio is an all-in-one environment designed for building AI-first applications with Google’s latest models. It supports Gemini, Imagen, Veo, and Gemma, allowing developers to experiment across multiple modalities in one place. The platform emphasizes vibe coding, enabling users to describe what they want and let AI handle the technical heavy lifting. Developers can generate complete, production-ready apps using natural language instructions. One-click deployment makes it easy to move from prototype to live application. Google AI Studio includes a centralized dashboard for API keys, billing, and usage tracking. Detailed logs and rate-limit insights help teams operate efficiently. SDK support for Python, Node.js, and REST APIs ensures flexibility. Quickstart guides reduce onboarding time to minutes. Overall, Google AI Studio blends experimentation, vibe coding, and scalable production into a single workflow.
-
Gemini Enterprise Agent PlatformGemini Enterprise Agent Platform is Google Cloud’s next-generation system for designing and managing advanced AI agents across the enterprise. Built as the successor to Vertex AI, it unifies model selection, development, and deployment into a single scalable environment. The platform supports a vast ecosystem of over 200 AI models, including Google’s latest Gemini innovations and popular third-party models. It offers flexible development tools like Agent Studio for visual workflows and the Agent Development Kit for deeper customization. Businesses can deploy agents that operate continuously, maintain long-term memory, and handle multi-step processes with high efficiency. Security and governance are central, with features such as agent identity verification, centralized registries, and controlled access through gateways. The platform also enables seamless integration with enterprise systems, allowing agents to interact with data, applications, and workflows securely. Advanced monitoring tools provide real-time insights into agent behavior and performance. Optimization features help refine agent logic and improve accuracy over time. By combining automation, intelligence, and governance, the platform helps organizations transition to autonomous, AI-driven operations. It ultimately supports faster innovation while maintaining enterprise-grade reliability and control.
-
LM-Kit.NETLM-Kit.NET is an enterprise-grade toolkit designed for seamlessly integrating generative AI into your .NET applications, fully supporting Windows, Linux, and macOS. Empower your C# and VB.NET projects with a flexible platform that simplifies the creation and orchestration of dynamic AI agents. Leverage efficient Small Language Models for on‑device inference, reducing computational load, minimizing latency, and enhancing security by processing data locally. Experience the power of Retrieval‑Augmented Generation (RAG) to boost accuracy and relevance, while advanced AI agents simplify complex workflows and accelerate development. Native SDKs ensure smooth integration and high performance across diverse platforms. With robust support for custom AI agent development and multi‑agent orchestration, LM‑Kit.NET streamlines prototyping, deployment, and scalability—enabling you to build smarter, faster, and more secure solutions trusted by professionals worldwide.
-
LTXMost AI video tools hand you a black box: closed weights, a subscription, and no way to see what is happening under the hood. LTX takes the opposite approach. Built by Lightricks, LTX is an open foundation model that generates and simulates across video, audio, and the physical world, and it puts the weights, the code, and the control in your hands. At the center of the model is LTX-2.5, a 22B-parameter dual-stream diffusion transformer that produces native 4K video at up to 50 frames per second, with audio and video generated together in a single pass rather than stitched together afterward. Artificial Analysis, an independent benchmarking group, currently ranks LTX among the top three AI video models in the world. You choose how you want to use it. Download the open weights and run LTX-2.5 on your own hardware. License the model for on-premise deployment backed by enterprise support. Or build directly on LTX Studio, the production suite that turns the model into a full creative workflow. Companies like ElevenLabs, Asteria Film Co., Magnopus, and NVIDIA already rely on LTX for their own work. LTX is not built for one-off social clips. It is infrastructure for teams that generate motion, audio, and physical environments as part of their own products and pipelines.
-
ClickLearnClickLearn simplifies complex business processes using popular software. You can create multi-format learning materials in any language and publish them to a 24/7 learning portal with just one click. A video walkthrough of the process, with narration in your preferred language. Put your learning to the test. This interactive simulation of your workplace allows you to test your knowledge without any hints. Interactive simulation of your workplace environment that guides you through the process. This guide is step-by-step. ClickLearn wrote this guide with perfectly cropped screenshots. ClickLearn Assist can be your go-to helper when you are stuck, need process help, or want to try a new process in the live system. You don't have to worry about making another mistake. All your learning materials can be auto-translated with a click of a button
-
StackAIStackAI is an enterprise AI automation platform that allows organizations to build end-to-end internal tools and processes with AI agents. It ensures every workflow is secure, compliant, and governed, so teams can automate complex processes without heavy engineering. With a visual workflow builder and multi-agent orchestration, StackAI enables full automation from knowledge retrieval to approvals and reporting. Enterprise data sources like SharePoint, Confluence, Notion, Google Drive, and internal databases can be connected with versioning, citations, and access controls to protect sensitive information. AI agents can be deployed as chat assistants, advanced forms, or APIs integrated into Slack, Teams, Salesforce, HubSpot, ServiceNow, or custom apps. Security is built in with SSO (Okta, Azure AD, Google), RBAC, audit logs, PII masking, and data residency. Analytics and cost governance let teams track performance, while evaluations and guardrails ensure reliability before production. StackAI also offers model flexibility, routing tasks across OpenAI, Anthropic, Google, or local LLMs with fine-grained controls for accuracy. A template library accelerates adoption with ready-to-use workflows like Contract Analyzer, Support Desk AI Assistant, RFP Response Builder, and Investment Memo Generator. By consolidating fragmented processes into secure, AI-powered workflows, StackAI reduces manual work, speeds decision-making, and empowers teams to build trusted automation at scale.
-
Google Cloud BigQueryBigQuery is a serverless, multicloud data warehouse that makes working with all types of data effortless, allowing you to focus on extracting valuable business insights quickly. As a central component of Google’s data cloud, it streamlines data integration, enables cost-effective and secure scaling of analytics, and offers built-in business intelligence for sharing detailed data insights. With a simple SQL interface, it also supports training and deploying machine learning models, helping to foster data-driven decision-making across your organization. Its robust performance ensures that businesses can handle increasing data volumes with minimal effort, scaling to meet the needs of growing enterprises. Gemini within BigQuery brings AI-powered tools that enhance collaboration and productivity, such as code recommendations, visual data preparation, and intelligent suggestions aimed at improving efficiency and lowering costs. The platform offers an all-in-one environment with SQL, a notebook, and a natural language-based canvas interface, catering to data professionals of all skill levels. This cohesive workspace simplifies the entire analytics journey, enabling teams to work faster and more efficiently.
-
Planview AdaptiveWorkPlanview AdaptiveWork, previously known as Clarizen, empowers PMOs and professional services teams of various sizes to achieve instant visibility across their operations, streamline workflows, proactively address potential risks, and enhance overall business outcomes. By aligning with the company’s strategic objectives, organizations can maximize workforce effectiveness, ensuring that teams concentrate on delivering the most critical tasks timely. It facilitates the tracking, management, and prioritization of work requests, guaranteeing that each request automatically encompasses all necessary information for execution. With bi-directional integration with your CRM and custom triggers in place, opportunity details can be effortlessly captured to aid in planning client projects. The platform automates and governs the various phases of the request lifecycle, including submission, scoring, prioritization, routing, and approval, thereby streamlining the pathway for converting requests into actionable projects, tasks, or work items. This comprehensive approach not only boosts efficiency but also fosters a culture of accountability and transparency within the organization.
-
SurveySparrowA platform for managing Omni-channel Experiences. You can do more than just survey. Power-up your experience management programs. All touch points can have an omnichannel experience. All data in one location. You can customize and share email surveys to increase open-rates. You can customize the subject, body, or share from an email address you choose. White-label your emails, and share. For feedback, share a QR code that can be scannable. Share the code with respondents. Respondents can scan the code to access the survey and take it. Generate multiple unique survey links for sharing surveys. These links can be tracked and used to measure survey performance. You can white-label your survey by using Custom Domain. You can embed surveys to engage customers and visitors on your website. You can embed the survey as a popup card, chatbot on your website, or inline embed. Our mobile SDK allows you to quickly create surveys and collect actionable information.
-
IONOS Cloud GPU ServersIONOS offers GPU Servers that deliver a high-performance computing framework aimed at managing tasks that demand significantly more power than standard CPU systems can provide. This infrastructure features top-tier NVIDIA GPUs, including the H100, H200, and L40s, in addition to specialized AI accelerators like Intel Gaudi, facilitating extensive parallel processing for demanding applications. By utilizing GPU-accelerated instances, the cloud infrastructure is enhanced with dedicated graphical processors, enabling virtual machines to execute intricate calculations and handle data-heavy tasks at a much faster rate compared to traditional servers. This solution is especially well-suited for fields such as artificial intelligence, deep learning, and data science, where training models on extensive datasets or executing rapid inference processes is necessary. Furthermore, it accommodates big data analytics, scientific simulations, and visualization tasks, including 3D rendering or modeling, that necessitate substantial computational capacity. As a result, organizations seeking to optimize their processing capabilities for complex workloads can greatly benefit from this advanced infrastructure.
Description
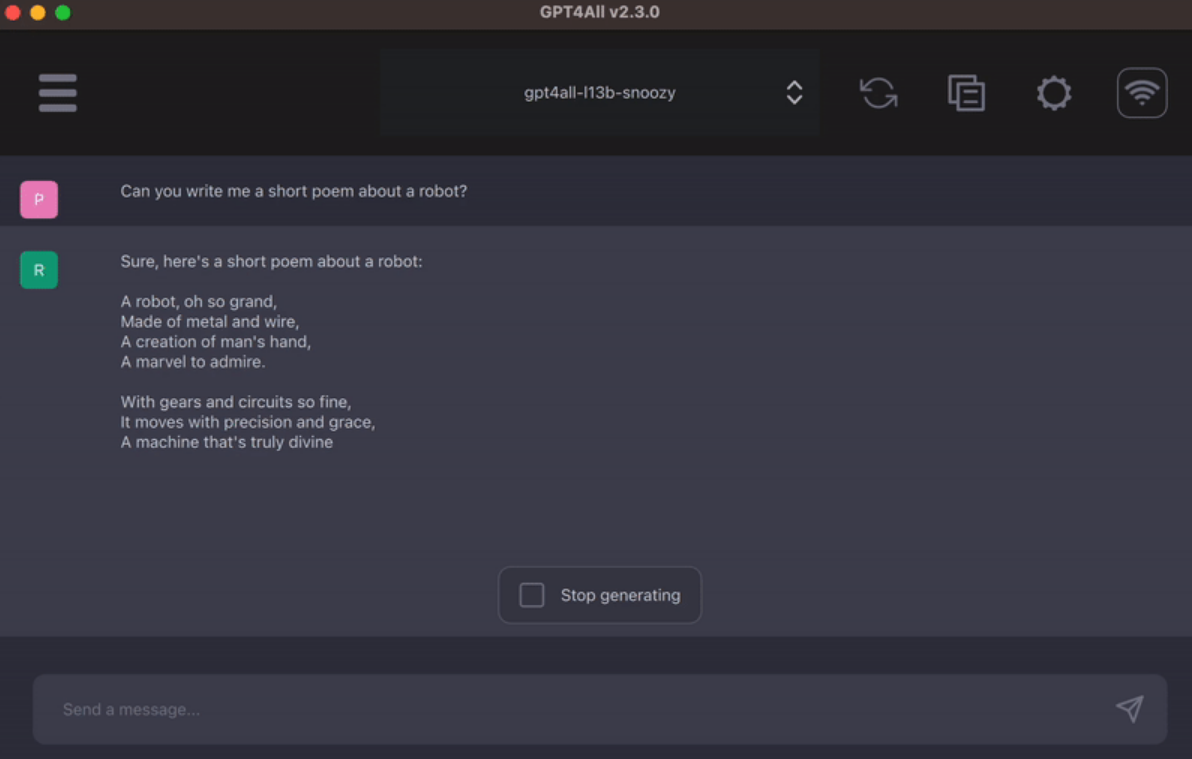
GPT4All represents a comprehensive framework designed for the training and deployment of advanced, tailored large language models that can operate efficiently on standard consumer-grade CPUs. Its primary objective is straightforward: to establish itself as the leading instruction-tuned assistant language model that individuals and businesses can access, share, and develop upon without restrictions. Each GPT4All model ranges between 3GB and 8GB in size, making it easy for users to download and integrate into the GPT4All open-source software ecosystem. Nomic AI plays a crucial role in maintaining and supporting this ecosystem, ensuring both quality and security while promoting the accessibility for anyone, whether individuals or enterprises, to train and deploy their own edge-based language models. The significance of data cannot be overstated, as it is a vital component in constructing a robust, general-purpose large language model. To facilitate this, the GPT4All community has established an open-source data lake, which serves as a collaborative platform for contributing valuable instruction and assistant tuning data, thereby enhancing future training efforts for models within the GPT4All framework. This initiative not only fosters innovation but also empowers users to engage actively in the development process.
Description
LLaVA, or Large Language-and-Vision Assistant, represents a groundbreaking multimodal model that combines a vision encoder with the Vicuna language model, enabling enhanced understanding of both visual and textual information. By employing end-to-end training, LLaVA showcases remarkable conversational abilities, mirroring the multimodal features found in models such as GPT-4. Significantly, LLaVA-1.5 has reached cutting-edge performance on 11 different benchmarks, leveraging publicly accessible data and achieving completion of its training in about one day on a single 8-A100 node, outperforming approaches that depend on massive datasets. The model's development included the construction of a multimodal instruction-following dataset, which was produced using a language-only variant of GPT-4. This dataset consists of 158,000 distinct language-image instruction-following examples, featuring dialogues, intricate descriptions, and advanced reasoning challenges. Such a comprehensive dataset has played a crucial role in equipping LLaVA to handle a diverse range of tasks related to vision and language with great efficiency. In essence, LLaVA not only enhances the interaction between visual and textual modalities but also sets a new benchmark in the field of multimodal AI.
API Access
Has API
No
API Access
Has API
No



Integrations
ExecuTorch
No
GPT-4
No
LLaMA-Factory
No
MindMac
Yes
ONLYOFFICE Docs
Yes
OpenLIT
Yes
Prem AI
Yes
Integrations
ExecuTorch
Yes
GPT-4
Yes
LLaMA-Factory
Yes
MindMac
No
ONLYOFFICE Docs
No
OpenLIT
No
Prem AI
No
Pricing Details
Free
Free Trial
No
Free Version
Yes
Pricing Details
Free
Free Trial
No
Free Version
Yes
Deployment
Web-Based
No
On-Premises
Yes
iPhone App
No
iPad App
No
Android App
No
Windows
Yes
Mac
Yes
Linux
Yes
Chromebook
No
Deployment
Web-Based
Yes
On-Premises
No
iPhone App
No
iPad App
No
Android App
No
Windows
No
Mac
No
Linux
No
Chromebook
No
Customer Support
Business Hours
No
Live Rep (24/7)
No
Online Support
Yes
Customer Support
Business Hours
No
Live Rep (24/7)
No
Online Support
Yes
Types of Training
Training Docs
Yes
Webinars
No
Live Training (Online)
No
In Person
No
Types of Training
Training Docs
Yes
Webinars
No
Live Training (Online)
Yes
In Person
No
Vendor Details
Company Name
Nomic AI
Founded
2022
Country
United States
Website
gpt4all.io
Vendor Details
Company Name
LLaVA
Website
llava-vl.github.io
Product Features
Artificial Intelligence
Chatbot
No
For Healthcare
No
For Sales
No
For eCommerce
No
Image Recognition
No
Machine Learning
No
Multi-Language
No
Natural Language Processing
No
Predictive Analytics
No
Process/Workflow Automation
No
Rules-Based Automation
No
Virtual Personal Assistant (VPA)
No
Chatbot
Call to Action
No
Context and Coherence
No
Human Takeover
No
Inline Media / Videos
No
Machine Learning
No
Natural Language Processing
No
Payment Integration
No
Prediction
No
Ready-made Templates
No
Reporting / Analytics
No
Sentiment Analysis
No
Social Media Integration
No
